Data Pipelines for AI: Quality Before Model Complexity
Enterprise AI depends on data that is current, permitted, traceable and understandable. Model quality cannot compensate for a weak data foundation.
AI projects often focus on model selection while data remains fragmented across documents, databases and SaaS platforms. A production system needs a pipeline that can collect, clean, classify, permission and monitor the information used by the model. The pipeline determines whether the output is grounded in trusted enterprise context.
Preserve ownership and permissions
The AI system should not expose information a user could not access directly. Pipelines need document-level or record-level permissions, source ownership and reliable identity mapping. Copying all data into one unrestricted index creates hidden risk.
Track freshness and lineage
Users should know when information was updated and where it came from. Pipelines should preserve source identifiers, timestamps and transformation history. This supports citations, correction and investigation when an answer is wrong.
Monitor retrieval and data quality
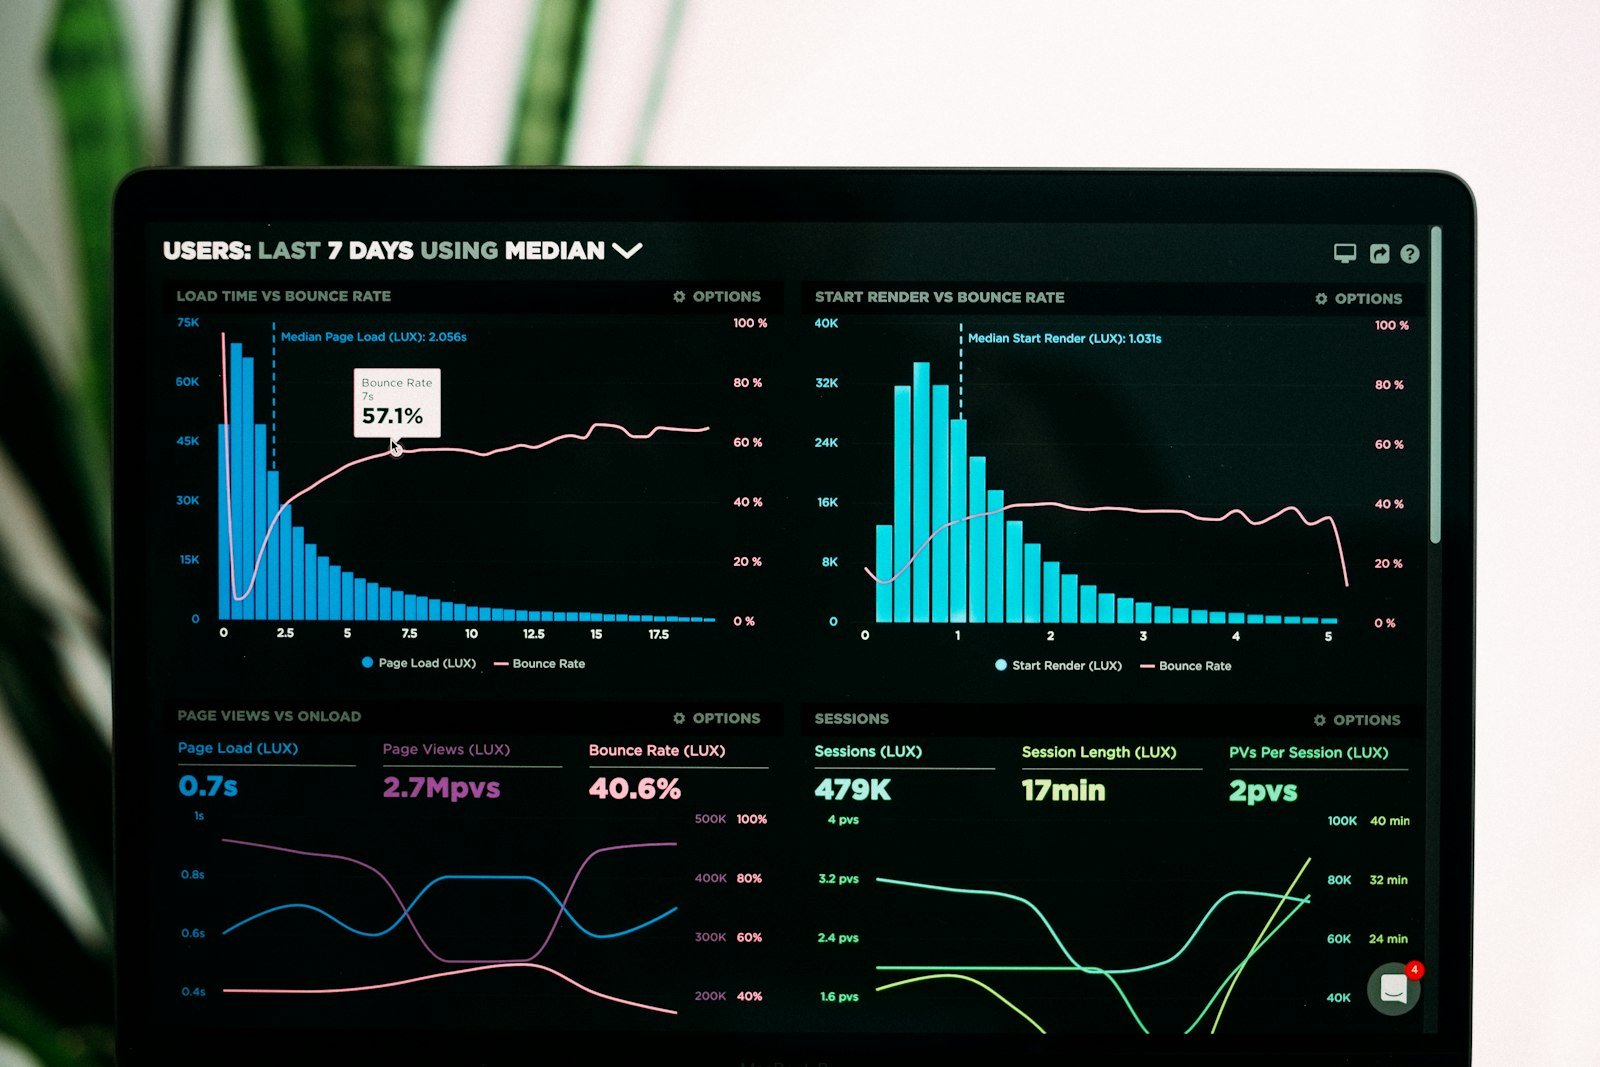
A model can generate a fluent response from poor retrieval. Teams should measure whether the right content was found, whether sources are complete and whether outdated documents are still active. Data quality monitoring should continue after launch.
What leaders can do next
- Inventory sources, owners, permissions and update frequency.
- Preserve source and access metadata through the pipeline.
- Define quality tests for ingestion and retrieval.
- Create a process to correct or remove unreliable content.
Closing perspective
AI quality begins before the prompt. A governed data pipeline creates the context, trust and accountability required for enterprise use.
Talk to an advisor.
Explore how F Creative Studio 360 can help you turn this idea into a secure, measurable initiative.
Contact our team